Sovereign 8s.is mirror of standardgalactic/carchive
- Python 85.7%
- HTML 11.7%
- Shell 2.3%
- Mako 0.1%
- JavaScript 0.1%
- Other 0.1%
| Filename | Latest commit message | Latest commit date |
|---|---|---|
 90c10c277d - Modified the title generation prompt to enforce stricter output constraints - Added numbered list format for clear instructions - Added explicit guidance to prevent model from responding to content requests - Emphasized single-line response requirement and maximum word count 🤖 Generated with [Claude Code](https://claude.ai/code) Co-Authored-By: Claude <noreply@anthropic.com> |
||
| alembic | ||
| alembic-new | ||
| chat | ||
| docs | ||
| my_output | ||
| my_outputs | ||
| old_alembic_problems | ||
| output | ||
| output_tests | ||
| scripts | ||
| src/carchive | ||
| tests | ||
| .gitignore | ||
| alembic.ini | ||
| api_server.py | ||
| apply_media_message_fix.sh | ||
| CLAUDE.md | ||
| comprehensive_fix.sh | ||
| conversation_render.html | ||
| criteria_Agent_Theory_20250120_012237.json | ||
| criteria_Agent_Theory_20250122_001721.json | ||
| criteria_article_20250121_233826.json | ||
| criteria_Edmund_Husserl_and_Phenomenology_20250120_010811.json | ||
| criteria_heart_sutra_science_20250120_012041.json | ||
| criteria_phenomenology_20250120_161336.json | ||
| disable_conda_auto.sh | ||
| disable_conda_completely.sh | ||
| environment.yml | ||
| fix_conda_base.sh | ||
| fix_conda_conflict.sh | ||
| fix_cors.sh | ||
| fix_dependencies.sh | ||
| gui_server.py | ||
| install_missing_deps.sh | ||
| install_missing_markdown_ext.sh | ||
| LICENSE | ||
| migrate_to_carchive.py | ||
| poetry.lock | ||
| pyproject.toml | ||
| pytest.ini | ||
| README.md | ||
| requirements.txt | ||
| restart_servers.sh | ||
| restart_servers_alt_ports.sh | ||
| run_api.sh | ||
| run_api_fixed.sh | ||
| run_api_mac.sh | ||
| run_api_venv.sh | ||
| run_api_with_cors.sh | ||
| run_gui.sh | ||
| run_gui_fixed.sh | ||
| run_gui_mac.sh | ||
| run_gui_standalone.sh | ||
| run_gui_venv.sh | ||
| run_gui_with_cors.sh | ||
| search_criteria.json | ||
| setup_carchive04_db.sh | ||
| setup_carchive_env.sh | ||
| setup_environment.sh | ||
| setup_mac_optimized_env.sh | ||
| setup_venv.sh | ||
| tree.txt | ||
Carchive
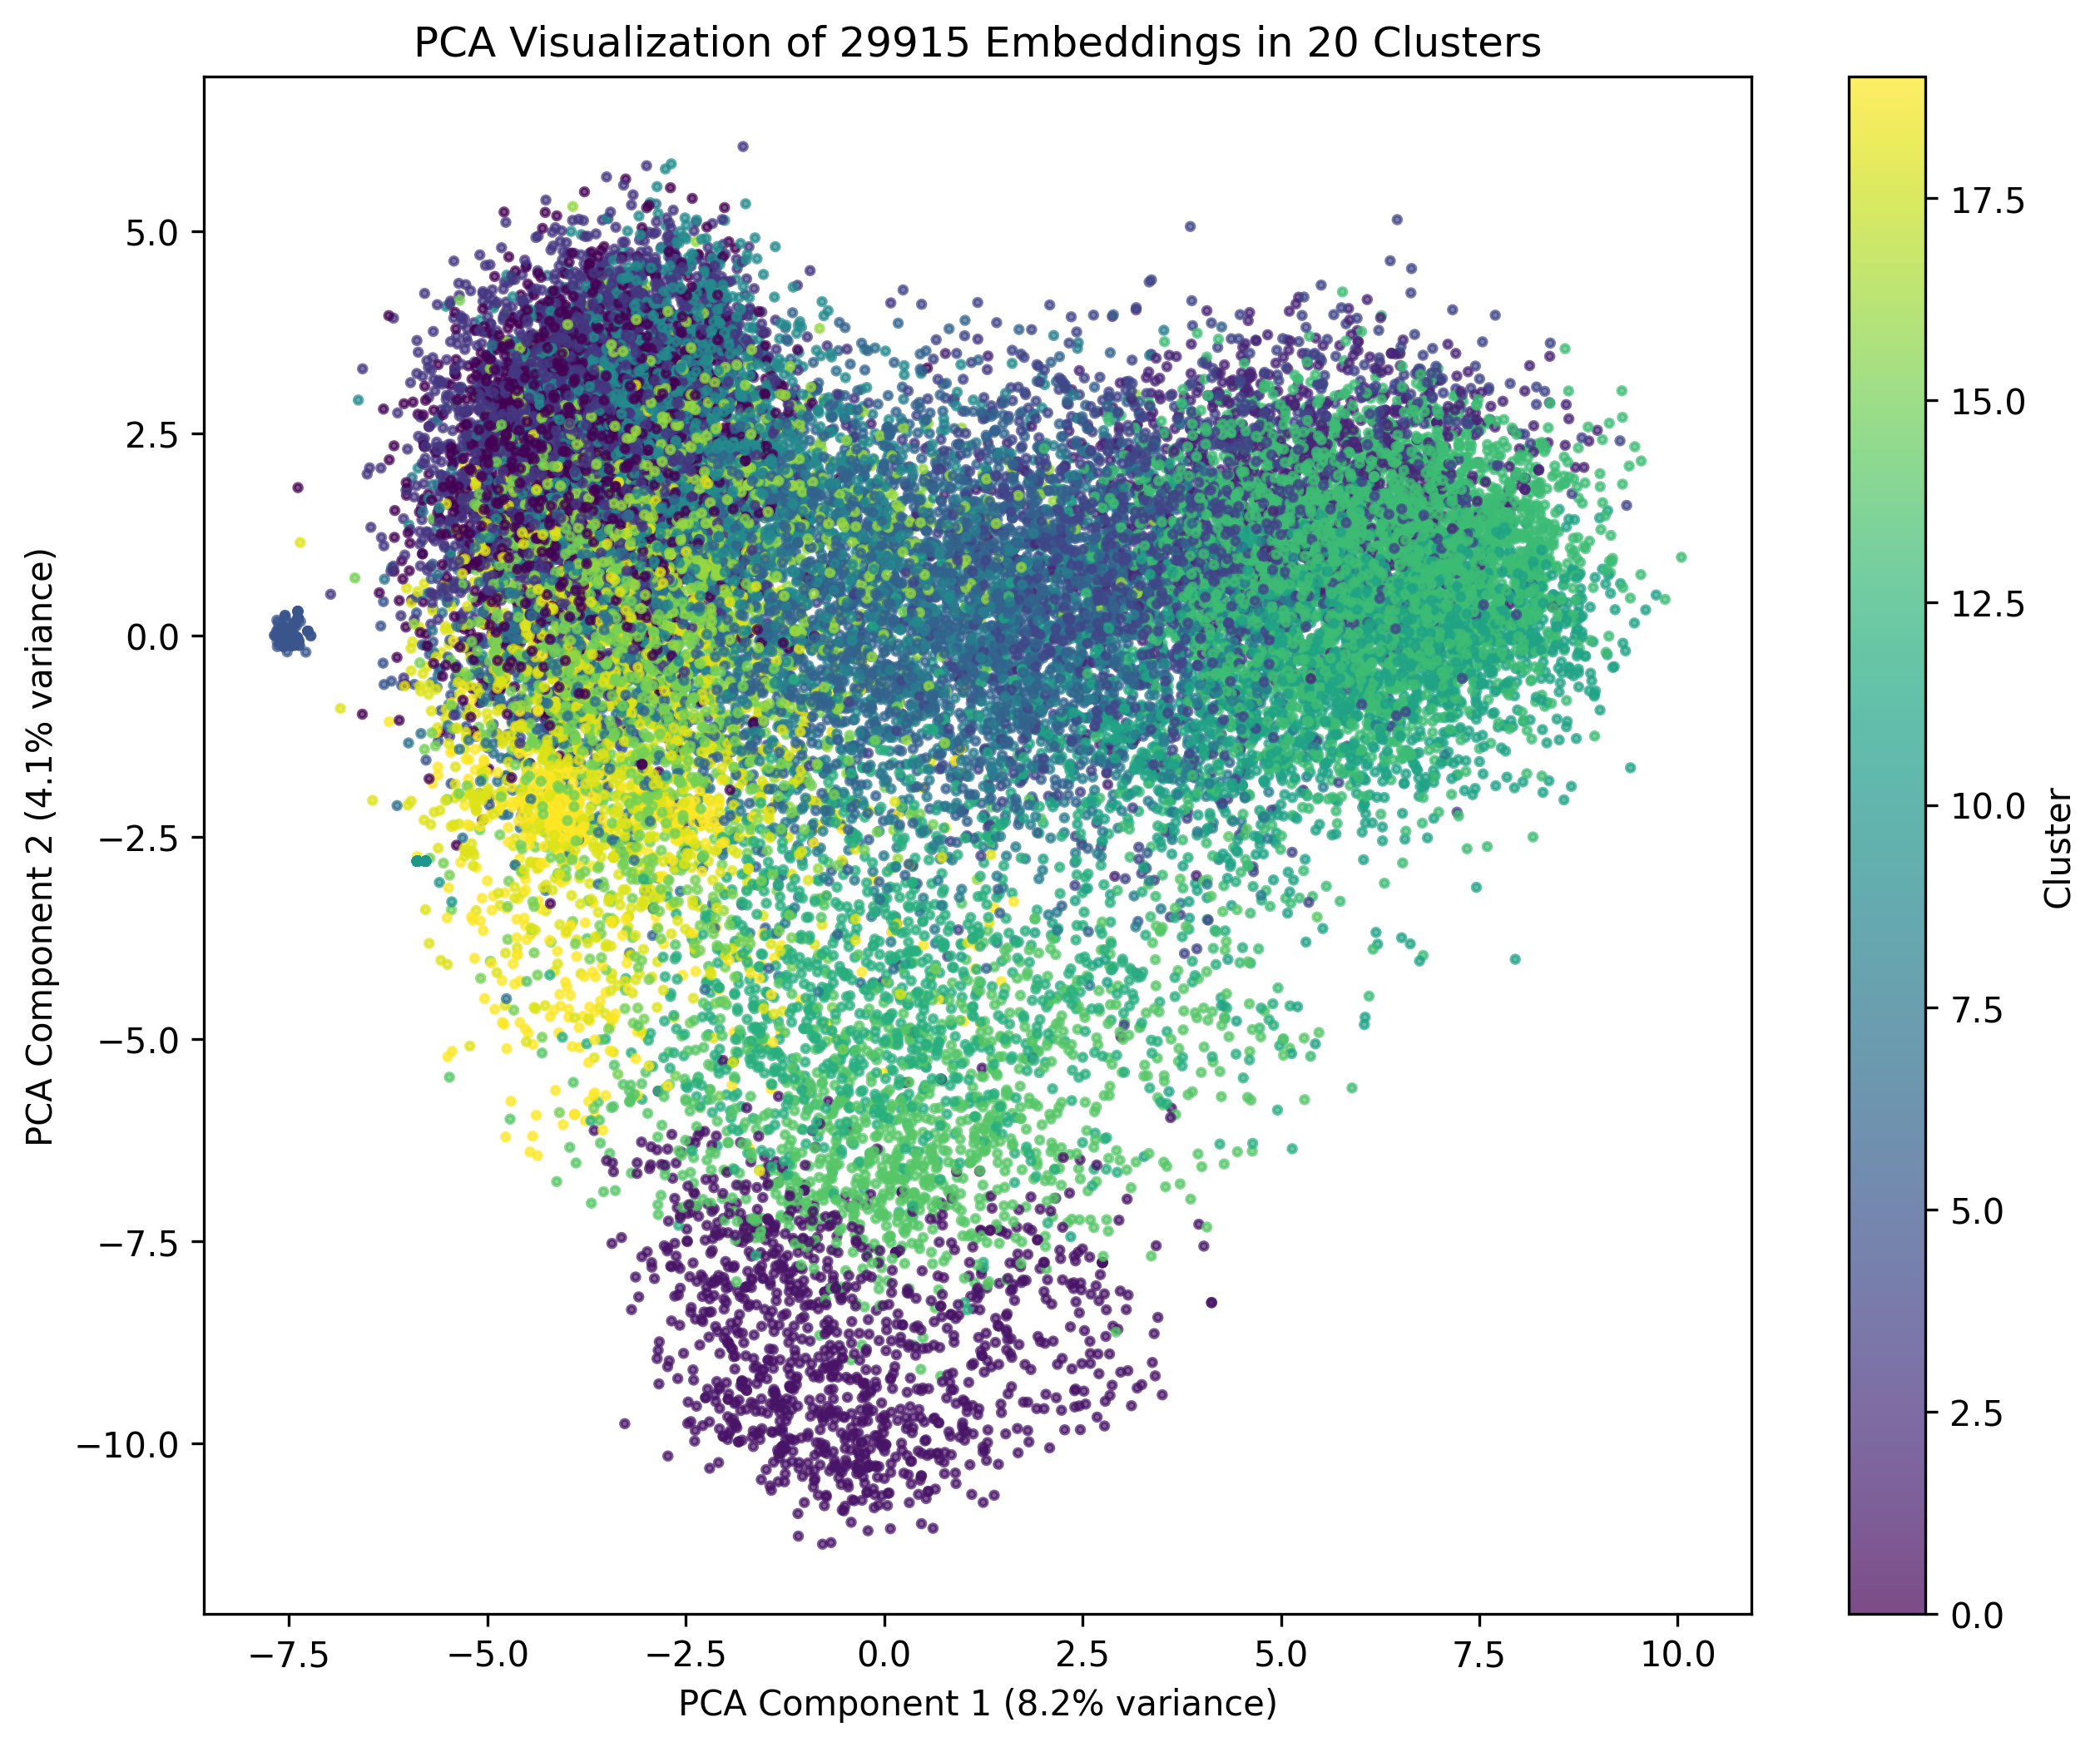
Carchive is a modern conversation archiving and analysis system designed to store, organize, search, and analyze text-based conversations using vector embeddings and AI. It supports importing conversations from multiple providers including ChatGPT, Claude and eventually others. Visualization of clusters:
Features
- Multi-Provider Support: Import from ChatGPT, Claude, and other LLM providers
- Conversation Archiving: Store and organize text-based conversations with metadata
- Vector Search: Find semantically similar content using pgvector
- AI Analysis: Generate summaries, insights, and connections between conversations
- Media Management: Link media files with conversation messages
- Collections: Organize conversations and messages into custom collections
- Statistics: View usage patterns and distribution by provider
Prerequisites
- Python 3.10+
- PostgreSQL with pgvector extension
- Poetry for dependency management
Installation
-
Clone this repository:
git clone https://github.com/temnoon/carchive.git cd carchive -
Install dependencies:
poetry install -
Set up environment variables (create a
.envfile):DATABASE_URL=postgresql://username:password@localhost:5432/carchive04_db ANTHROPIC_API_KEY=your_anthropic_api_key # Optional for AI features OPENAI_API_KEY=your_openai_api_key # Optional for AI features OLLAMA_URL=http://localhost:11434 # Optional for local embeddings -
Create and initialize the database:
# Create the database with pgvector support
./setup_carchive04_db.sh

# Or run the migrations manually
poetry run alembic upgrade head
CLI Commands
Carchive provides a comprehensive CLI interface for managing conversations and performing analysis.
Main CLI
poetry run carchive [OPTIONS] COMMAND [ARGS]...
Available Commands:
api- Commands for managing the API servercollection- Commands to manage or create collectionsconv2- Commands for managing conversationsconversation- Legacy conversation commandscluster- Commands for clustering and visualizing embeddings by topicembed- Commands for generating and storing embeddingsgencom- Commands for generating AI comments on content (see Gencom Guide)ingest- Commands to ingest chat data into the databasemedia- Commands for managing media filesmigrate- Migration tools for carchivesearch- Commands to search conversations/messages/chunkssummarize- Commands for generating summaries using content agents
Migration from LLM Services
# Migrate ChatGPT archive
poetry run carchive migrate chatgpt --db-name=carchive04_db --db-user=carchive_app path/to/conversations.json

# Migrate Claude archive
poetry run carchive migrate claude --db-name=carchive04_db --db-user=carchive_app path/to/claude_archive
Conversation Management
# List all conversations
poetry run carchive conv2 list

# Filter conversations by provider
poetry run carchive conv2 list --provider claude

# Get conversation details
poetry run carchive conv2 get <conversation-id> --with-messages

# View conversation statistics by provider
poetry run carchive conv2 stats

# List available providers
poetry run carchive conv2 providers

# Export a conversation to JSON
poetry run carchive conv2 export <conversation-id> output.json
Search
# Basic search
poetry run carchive search messages "your search term"

# Detailed search with context
poetry run carchive search detailed "your search term"

# Advanced search using saved criteria
poetry run carchive search advanced --criteria-file criteria.json --output-file results.html
Media Management
# Scan and link media files
poetry run carchive media scan-and-link --media-dir /path/to/media --recursive

# Analyze media distribution
poetry run carchive media analyze-media-distribution
Collections
# Create a new collection
poetry run carchive collection create "Collection Name" --description "Description"

# List existing collections
poetry run carchive collection list

# Render a collection to HTML
poetry run carchive collection render <collection-id> --output-file collection.html
Embeddings
# Generate embeddings for all messages
poetry run carchive embed all --min-word-count 10

# Generate embeddings for specific roles
poetry run carchive embed all --min-word-count 10 --include-roles user assistant

# Generate embeddings with custom model
poetry run carchive embed all --min-word-count 10 --provider openai --model-version text-embedding-ada-002

# Generate embeddings for a specific collection
poetry run carchive embed collection <collection-id>

# Generate summaries for messages with embeddings
poetry run carchive embed summarize --provider llama3.2
Clustering and Topic Analysis
# Analyze embeddings to find optimal cluster count
poetry run carchive cluster analyze

# Create clusters with KMeans algorithm and visualize
poetry run carchive cluster kmeans --n-clusters=20 --visualization

# Use density-based clustering with DBSCAN
poetry run carchive cluster dbscan --visualization

# Create hierarchical clusters with topic and subtopic levels
poetry run carchive cluster hierarchical --primary-clusters=5 --secondary-clusters=3
For detailed documentation on clustering capabilities, see Embedding Clusters Guide.
API Server
# Run the API server
poetry run carchive api serve --host 0.0.0.0 --port 8000
Development
# Run tests
poetry run pytest

# Add dependency
poetry add package_name

# Set up environment
./setup_carchive_env.sh
Database Structure
The carchive04_db uses a normalized structure with the following key tables:
- providers - Information about LLM providers (ChatGPT, Claude, etc.)
- conversations - Main conversation metadata
- messages - Individual messages with content and metadata
- media - Media file references and metadata
- message_media - Links between messages and media
- collections/collection_items - For organizing conversations and messages
- embeddings - Vector embeddings for semantic search