| Filename | Latest commit message | Latest commit date |
|---|---|---|
| assets | ||
| .gitattributes | ||
| README.md | ||

Demystifying Video Reasoning


Overview
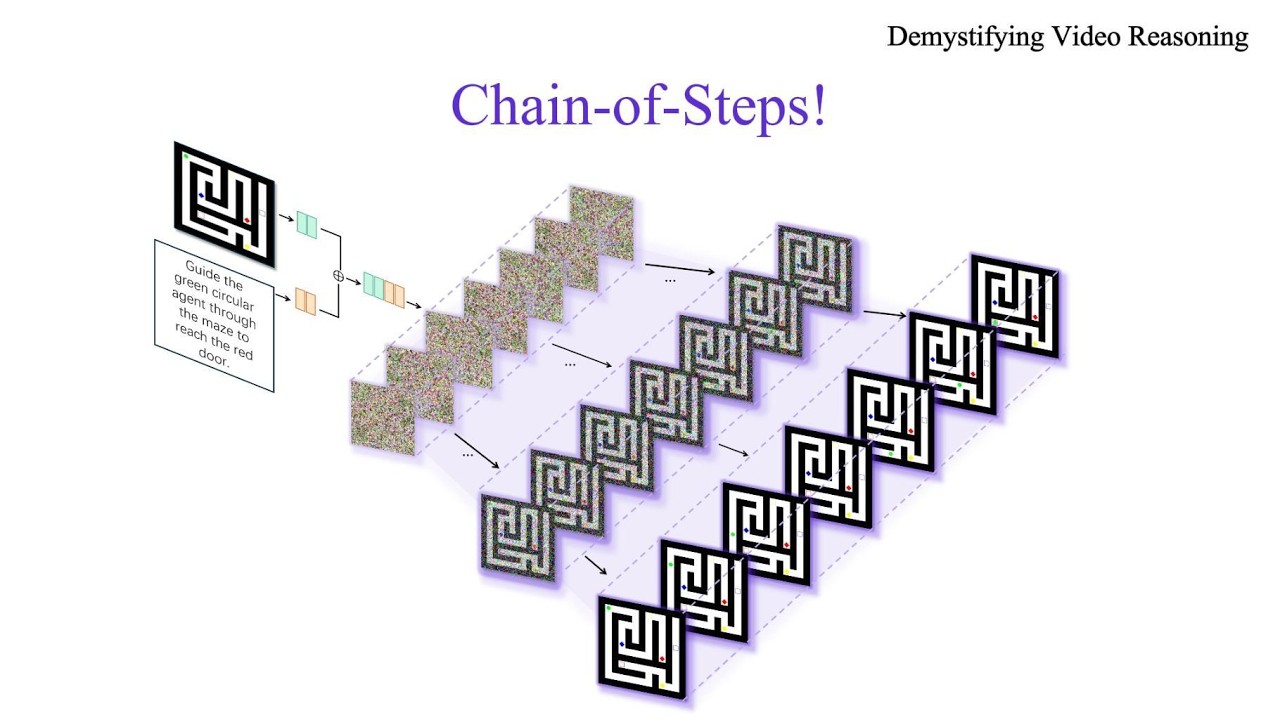
This is the official repository for Demystifying Video Reasoning.
Stay tuned for more updates!
Introduction
Recent advances in video generation have revealed an unexpected phenomenon: diffusion-based video models exhibit non-trivial reasoning capabilities. Prior work attributes this to a Chain-of-Frames (CoF) mechanism, where reasoning is assumed to unfold sequentially across video frames. In this work, we challenge this assumption and uncover a fundamentally different mechanism. We show that reasoning in video models instead primarily emerges along the diffusion denoising steps. Through qualitative analysis and targeted probing experiments, we find that models explore multiple candidate solutions in early denoising steps and progressively converge to a final answer, a process we term Chain-of-Steps (CoS). Beyond this core mechanism, we identify several emergent reasoning behaviors critical to model performance: (1) working memory, enabling persistent reference; (2) self-correction and enhancement, allowing recovery from incorrect intermediate solutions; and (3) perception before action, where early steps establish semantic grounding and later steps perform structured manipulation. During a diffusion step, we further uncover self-evolved functional specialization within Diffusion Transformers, where early layers encode dense perceptual structure, middle layers execute reasoning, and later layers consolidate latent representations. Motivated by these insights, we present a simple training-free strategy as a proof-of-concept, demonstrating how reasoning can be improved by ensembling latent trajectories from identical models with different random seeds. Overall, our work provides a systematic understanding of how reasoning emerges in video generation models, offering a foundation to guide future research in better exploiting the inherent reasoning dynamics of video models as a new substrate for intelligence.
News
- [2026-03-20] We have released the paper Demystifying Video Reasoning.
Release Plan
- [] Intermediate steps decoding tool
- [] Layer-wise token-Level visualization tool
Citation
If you find this work useful, please cite our paper:
@article{wang2026demystifing,
  title={Demystifing Video Reasoning},
  author={Wang, Ruisi and Cai, Zhongang and Pu, Fanyi and Xu, Junxiang and Yin, Wanqi and Wang, Maijunxian and Ji, Ran and Gu, Chenyang and Li, Bo and Huang, Ziqi and Deng, Hokin and Lin, Dahua and Liu, Ziwei and Yang, Lei},
  journal={arXiv preprint arXiv:2603.16870},
  year={2026}
}